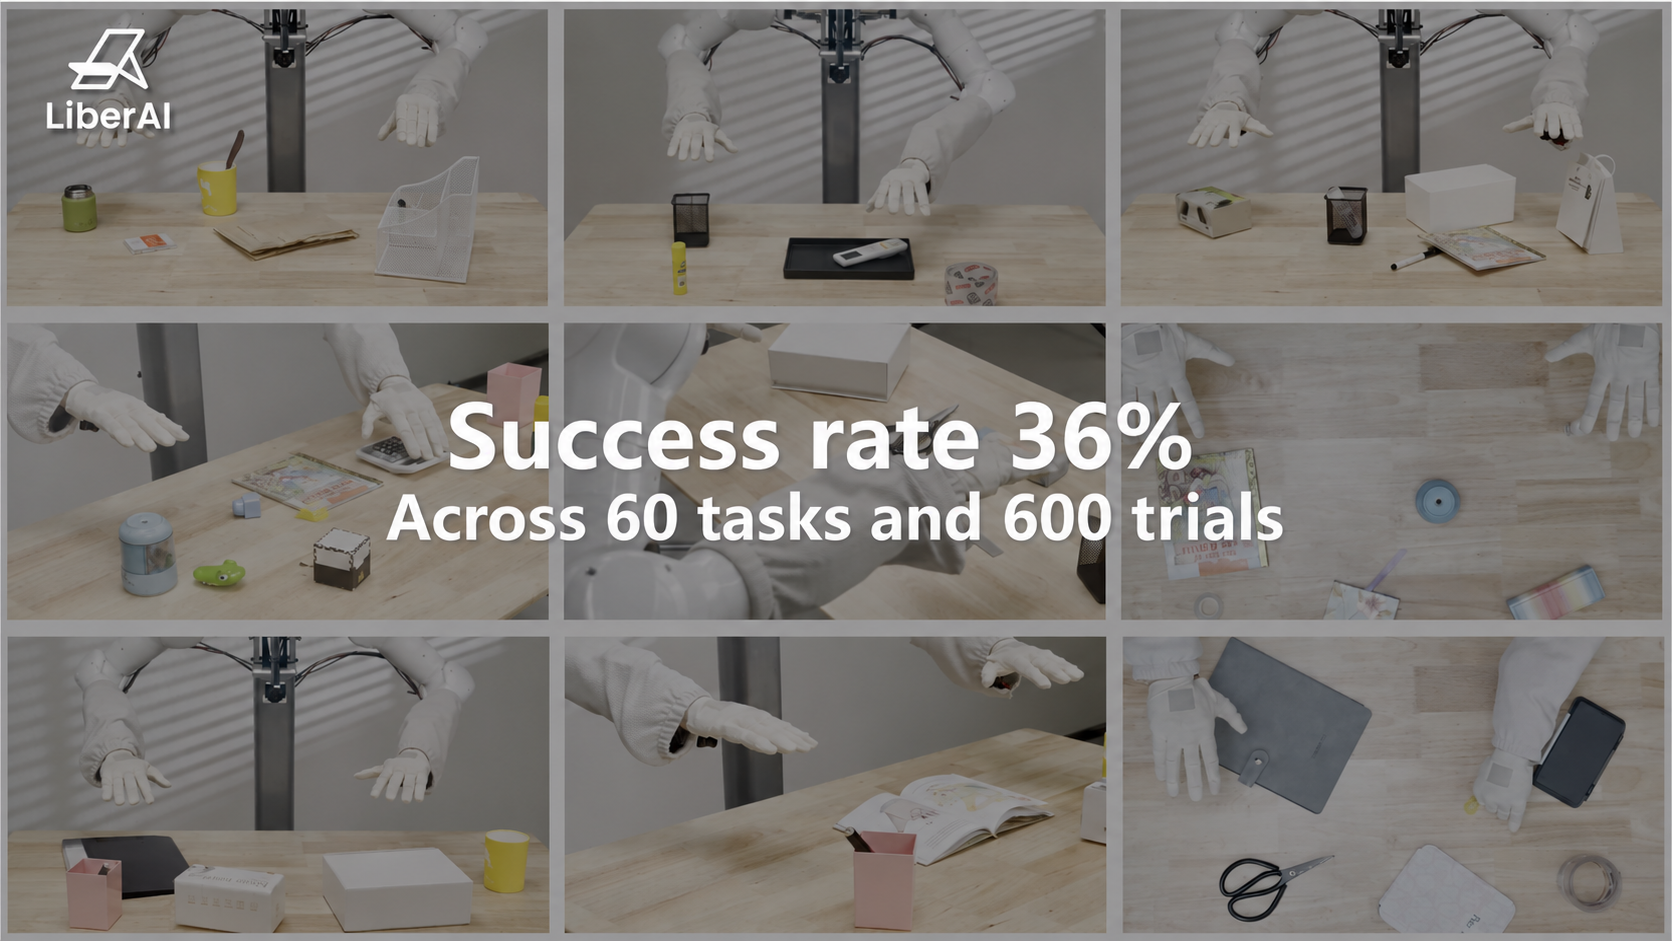

Liber-0 learns from 2.2M+ hours of human experience, demonstrating zero-shot manipulation across 60 GPT-6-proposed tasks, including multi-step tasks.
NEW YORK CITY, NY, UNITED STATES, November 4, 2026 /EINPresswire.com/ — LiberAI today introduced Liber-0, a World Action Model (WAM) that achieved a 36.0% overall success rate across 600 trials covering 60 robot manipulation tasks proposed by GPT-6. The evaluated model completed these tasks without training on robot demonstrations collected specifically for them, suggesting that human experience can help reduce the need to demonstrate each target task on a robot.
The evaluation covered 20 pick-and-place tasks, 20 other manipulation tasks, and 20 challenging non-pick-and-place and long-horizon tasks, each tested 10 times. Liber-0 achieved success rates of 63.5%, 34.0%, and 10.5% across the three groups, respectively. LiberAI defines this capability as task-level zero-shot generalization: the model was trained on robot data during pretraining, but not on robot demonstrations collected for the evaluated tasks.
Turning Human Experience into Robot Skills:
Human video shows people opening drawers, folding objects and handling tools, but it does not directly tell a robot how to move its fingers or adjust for a different body. Differences in camera viewpoints, motion capabilities and body structure make this transfer difficult.
LiberAI addresses these challenges through two complementary approaches: action grounding and embodiment alignment.
Liber-0 uses hand poses and trajectories recorded by LiberSense Glove, LiberAI’s data-collection system, to connect human video with measured physical actions. It jointly predicts future visual frames and actions, allowing it to learn from both human video without action labels and recordings with explicit motion supervision.
Embodiment alignment brings robot observations and movement capabilities closer to those represented in human demonstrations. LiberAI’s robotic platform, LEO, incorporates dexterous hands, articulated wrists and waist, and camera configurations aligned with human data collection. A Unified Embodiment Representation tells the model about body dimensions and how joints move, helping it adapt learned actions to the robot’s body.
Together, these designs aim to make human experience more transferable to robot execution, rather than relying on direct imitation of human motion.
Evidence for Scaling Human-to-Robot Transfer:
LiberAI reports several experiments examining how action-grounded human experience affects robot learning.
Action-grounded data versus web video. In controlled single-source pretraining experiments followed by the same robot post-training, 10,000 hours of glove recordings outperformed 2 million hours of web human video on both pick-and-place and non-pick-and-place manipulation benchmarks. The full staged Liber-0 recipe performed best among the evaluated configurations, highlighting the value of combining broad human video with reliable motion supervision and embodiment alignment.
Learning with fewer robot demonstrations. In an eight-task evaluation, combining 25% of the robot demonstration pool with the full glove demonstration pool achieved a progress score of 75.6, compared with 72.8 using the full robot demonstration pool alone. The two complete data pools contained equal numbers of demonstrations.
Learning behaviors absent from robot demonstrations. When a policy’s robot demonstrations covered only pick-and-place tasks, adding glove recordings of other manipulation actions raised its non-pick-and-place progress score from 2.2 to 47.5. Broader glove data increased it to 54.6, close to the 56.3 achieved with robot demonstrations covering both task groups.
These experiments use progress scores on a scale of 0 to 100, measuring partial task completion rather than task success rates. They are separate from the 60-task zero-shot evaluation.
Toward Generalizable Robot Intelligence:
LiberAI’s goal is to reduce how often a new robot task requires a new set of robot demonstrations. Liber-0’s results suggest that human experience can help, although performance on challenging and long-horizon tasks remains limited.
Further details on Liber-0’s model architecture, training approach, and evaluations are available in the technical blog. Watch the demonstration videos via Liber-0 in Action, or explore the model through Interactive Simulation.
PR
LiberAI
Legal Disclaimer:
EIN Presswire provides this news content “as is” without warranty of any kind. We do not accept any responsibility or liability
for the accuracy, content, images, videos, licenses, completeness, legality, or reliability of the information contained in this
article. If you have any complaints or copyright issues related to this article, kindly contact the author above.

Media gallery